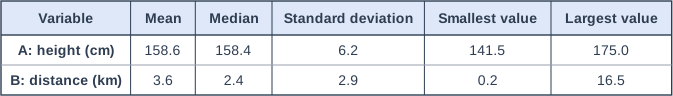
A school has data on two variables for the 150 girls in Year 9.
Variable A: height, in cm
Variable B: the distance from home to school, in km
The table shows some statistics for each variable.
Mr Hill wants to model one of the variables with a normal distribution.
You may use skew \(= \dfrac{3(\text{mean} - \text{median})}{\text{standard deviation}}\)
Which variable is more suitable for a normal model? You must show your working.
Model answer
Skew for A \(= \dfrac{3(158.6 - 158.4)}{6.2} = 0.097\), which is very close to 0.
Skew for B \(= \dfrac{3(3.6 - 2.4)}{2.9} = 1.24\), which is positive and not close to 0.
For A, mean ± 3 standard deviations = 158.6 ± 18.6, from 140.0 cm to 177.2 cm, and the smallest and largest heights are both inside this range.
For B, the largest distance, 16.5 km, is (16.5 − 3.6) ÷ 2.9 = 4.4 standard deviations above the mean, which would be very unusual for a normal distribution. Also, mean − 2 standard deviations = 3.6 − 5.8, which is below 0, but a distance cannot be negative.
So variable A, height, is more suitable for a normal model: the heights are roughly symmetrical, while the distances are positively skewed.
Explanation
A normal model needs data that are symmetrical and bell-shaped, with the mean, median and mode about equal. The skew of A is almost 0 and all its values lie within 3 standard deviations of the mean, but B has a large positive skew and a value more than 4 standard deviations above the mean, which is typical of distances (most students live near the school and a few live a long way away). A conclusion needs at least one statistic to support it.