
Level:
Correct: 0
Incorrect: 0
Marks: 0/0
Exam Practice
Course:
Topics:
Edexcel GCSE Statistics (Higher Paper 1) Smart practice A mixed round aimed at your weak spots
Unit 1
The statistical enquiry cycle
Statistical enquiry cycle stages 1 and 2; (a) Planning: 1a.01, 1a.02, 1a.03
Statistical enquiry cycle: planning and collecting
Statistical enquiry cycle stages 3, 4 and 5
Statistical enquiry cycle: interpreting and evaluating
Unit 2
The collection of data
(b) Types of data: 1b.01, 1b.02, 1b.03
Types of data and variables
(b) Types of data: 1b.04; (d) Collecting data: 1d.01, 1d.02
Primary and secondary data, reliability and validity
(c) Population and sampling: 1c.01, 1c.02, 1c.03
Populations, sampling frames and non-random sampling
(c) Population and sampling: 1c.04, 1c.05
Random and systematic sampling
(c) Population and sampling: 1c.06
Stratified sampling
(d) Collecting data: 1d.05, 1d.06
Problems with collected data and cleaning data
Unit 3
Processing, representing and analysing data
(a) Tabulation, diagrams and representation: 2a.01
Tabulation, tallies, pictograms and two-way tables
(a) Tabulation, diagrams and representation: 2a.01, 2a.02
Pie charts and comparative pie charts
(a) Tabulation, diagrams and representation: 2a.01
Stem and leaf diagrams
(a) Tabulation, diagrams and representation: 2a.02
Population pyramids, choropleth maps and 2D and 3D diagrams
(a) Tabulation, diagrams and representation: 2a.04
Histograms and frequency density
(a) Tabulation, diagrams and representation: 2a.05, 2a.06, 2a.07, 2a.08
Choosing representations and misleading diagrams
(a) Tabulation, diagrams and representation: 2a.09, 2a.10
Skewness
(b) Measures of central tendency: 2b.01, 2b.02, 2b.03
Mode, median and mean
(b) Measures of central tendency: 2b.01
Weighted mean and geometric mean
(c) Measures of dispersion: 2c.01, 2c.06
Standard deviation and standardised scores
(a) Tabulation, diagrams and representation: 2a.03; (c) Measures of dispersion: 2c.02, 2c.03
Box plots and outliers
(b) Measures of central tendency: 2b.03; (c) Measures of dispersion: 2c.04, 2c.05
Comparing distributions
(d) Further summary statistics: 2d.01
Index numbers
(d) Further summary statistics: 2d.02
Rates of change
(e) Scatter diagrams and correlation: 2e.01, 2e.02, 2e.03
Scatter diagrams, correlation and causation
(e) Scatter diagrams and correlation: 2e.04
Lines of best fit and regression lines
(e) Scatter diagrams and correlation: 2e.05, 2e.06, 2e.07, 2e.08
Spearman's rank and product moment correlation coefficients
(f) Time series: 2f.01, 2f.02; (b) 2b.01 mean seasonal variation
Time series, moving averages and seasonal variation
(g) Quality assurance: 2g.01, 2g.02
Quality assurance and control charts
(h) Estimation: 2h.01, 2h.02, 2h.03
Estimation, sample size and capture-recapture
Unit 4
Probability
3. Probability: 3p.01, 3p.02, 3p.03, 3p.04
Probability, expected frequency and risk
3. Probability: 3p.05, 3p.06, 3p.10
Experimental and theoretical probability and bias
3. Probability: 3p.11
Binomial distribution
3. Probability: 3p.12, 3p.13
Normal distribution
Avg
score:
–
Topics
done:
0/40

Experimental and theoretical probability and bias

Practise 12 exam-style questions on Experimental and theoretical probability and bias for Edexcel GCSE Statistics (Higher Paper 1). Write your answer as you would in the exam and get it marked in seconds against the mark scheme, point by point, with the Study Helper on hand if you get stuck.

  • 12 questions
  • 1–5 marks each
  • Instant marking
  • No sign-up needed
12 questions, marked as you go

Sample questions with model answers

Here are 4 of the questions in this topic, each with a model answer, an explanation of why it earns the marks and the mark scheme an examiner would use.

Question 1

1 mark

Each day, the manager of a small shop chooses 5 of her customers at random and records the number of items each of them buys. She uses the mean of these 5 numbers as her estimate of the mean number of items bought by a customer.

Her estimates for four days are 3.2, 7.8, 4.4 and 9.0 items.

Suggest how the manager could get a more reliable estimate of the mean number of items bought by a customer. Give a reason for your answer.

Model answer

She should use a much larger random sample, for example 50 customers each day, or combine the samples from several days. With only 5 customers, one or two who buy a lot (or very little) change the mean a lot, which is why her estimates vary so much. A larger sample generally gives a better estimate of the mean for all customers.

Explanation

Just as more trials give a better estimate of a probability, a larger random sample generally gives a better estimate of a population mean. The estimates from samples of 5 vary a lot (from 3.2 to 9.0) because a few unusual customers have a big effect on a small sample. The reason must be about the size of the sample.

Mark scheme
  1. 1 mark

    B1 for use a larger (random) sample, e.g. 50 customers, or combine the samples from several days, because a larger sample generally gives a better estimate of the (population) mean

    The suggestion and the reason are both needed. Accept 'ask many more customers, so that one or two unusual customers have less effect on the mean' oe. B0 for a larger sample with no reason, or with a reason not about sample size (e.g. 'so it is fair'). B0 for suggestions that are not about sample size, e.g. 'use the median' or 'choose customers who buy a lot'. Ignore extraneous non-contradictory comments.
Question 2

2 marks

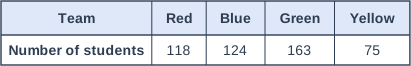
For sports day, a school uses an app to put each of its 480 students into one of four teams: Red, Blue, Green or Yellow. Each student should be equally likely to be put into any of the four teams.

The table shows the number of students that the app put into each team.

The PE teacher thinks that the app may not be choosing the teams at random.

Use expected frequencies to comment on the teacher's view. You must show your working.

Table with columns "Team", "Red", "Blue", "Green", "Yellow". Team: Number of students; Red: 118; Blue: 124; Green: 163; Yellow: 75.

Model answer

If the app is choosing at random, each team has probability 1/4, so the expected number in each team is 480 ÷ 4 = 120
Red (118) and Blue (124) are close to 120.
Green has 163, which is 43 more than expected, and Yellow has 75, which is 45 fewer than expected.
These differences are too large to be just chance, so the results support the teacher's view: the app may be biased towards Green and against Yellow.

Explanation

Compare each observed frequency with the expected frequency from the theoretical probability. Small differences from 120, like 118 and 124, are expected by chance, but differences of more than 40 out of 480 suggest bias. A comment that the numbers are 'not equal' does not take account of chance variation, and the conclusion must refer to the teams that are far from 120.

Mark scheme
  1. 1 mark

    M1 for the expected frequency for each team, \(480 \div 4 = 120\), or the theoretical probability 0.25 compared with a relative frequency, e.g. \(\dfrac{163}{480}\) (= 0.34) or \(\dfrac{75}{480}\) (= 0.156)

    oe.

  2. 1 mark

    A1 for a conclusion that supports the teacher's view, with a reason, e.g. Green (163) has many more and Yellow (75) has many fewer students than the 120 expected, so the app may be biased (towards Green and against Yellow)

    A conclusion and a comparison of Green or Yellow (163 or 75, or their relative frequencies) with the expected value (120 or 0.25) are both needed. Accept a comment that Red and Blue are close to 120 but Green and Yellow are not. A0 for 'the numbers are not all 120' (small differences from 120 are expected by chance). A0 for a conclusion based only on Red or Blue. Answer only scores 0.

Question 3

3 marks

Kofi flips a fair coin 40 times. It lands on heads 28 times, so the relative frequency of heads is 0.7

Kofi says,
"Tails must now be more likely than heads, so that the results balance out."

Kofi flips the coin another 960 times.

Work out the expected relative frequency of heads after all 1000 flips. Use your answer to comment on Kofi's statement.

Model answer

Expected number of heads in the next 960 flips = 0.5 × 960 = 480
Expected total number of heads = 28 + 480 = 508
Expected relative frequency = 508 ÷ 1000 = 0.508
Kofi is wrong. On every flip the probability of heads is still 0.5: tails does not become more likely. The relative frequency moves from 0.7 towards 0.5 because the first 40 flips become only a small part of the 1000 flips, not because the results 'balance out'.

Explanation

As the number of trials increases, the relative frequency tends towards the theoretical probability. This happens because the early results are swamped by many later results, each with the same probability, not because later results make up for earlier ones (the 'gambler's fallacy'). Using 0.5 for the later flips and adding the 28 heads already seen gives 0.508.

Mark scheme
  1. 1 mark

    M1 for \(0.5 \times 960\) (= 480) or \(28 + 0.5 \times 960\) (= 508)

    oe.

  2. 1 mark

    A1 for 0.508 oe

    Accept \(\dfrac{508}{1000}\), \(\dfrac{127}{250}\) or 50.8%. Accept 0.51 with correct working. An answer of 0.5 scores M0A0 unless 480 or 508 is seen (then M1A0). A correct answer (0.508) with no working scores M1A1.

  3. 1 mark

    B1 for Kofi is wrong, with a reason, e.g. the probability of heads is still 0.5 on each flip (the coin does not remember earlier flips); the relative frequency gets closer to 0.5 only because the first 40 flips become a small part of the total

    oe. A decision that Kofi is wrong and a correct reason are both needed. Accept 'tails is not more likely; 0.508 is close to 0.5 even though heads is not less likely in the later flips'. B0 for 'Kofi is wrong because the coin is fair' with no further reason.

Question 4

4 marks

A supermarket says that people cannot taste the difference between its own cola and a well-known brand of cola.

To test this, each of 240 people tasted three cups of cola. Two of the cups contained the same cola and the third cup contained the other cola. Each person had to choose the cup that was different.

If a person cannot taste the difference, the probability that they choose the different cup is \(\dfrac{1}{3}\).

112 of the 240 people chose the different cup.

Use the results to assess the supermarket's statement. You must show your working.

The supermarket says that the test may not have been carried out well. Give one possible reason, to do with how the test was carried out, that could explain the result.

Model answer

If people cannot taste the difference, the expected number who choose the different cup is \(\dfrac{1}{3} \times 240 = 80\)
112 people chose it: 32 more than expected. The relative frequency is \(\dfrac{112}{240} = 0.47\) compared with \(\dfrac{1}{3} = 0.33\), a large difference for 240 people.
So the results do not support the supermarket's statement: either people can taste the difference, or there was bias in the test.
A possible reason: the two colas may look different, for example in colour or in how fizzy they are, so people could pick out the different cup by looking instead of tasting.

Explanation

The theoretical probability of 1/3 gives an expected 80 correct choices from 240 people who are only guessing. 112 is far more than chance would usually give, so either people can tell the colas apart or something in the design of the test helped them. Good reasons explain how the different cup could be identified without tasting, such as the colour or fizz of the drinks or the position of the cups.

Mark scheme
  1. 1 mark

    M1 for \(\dfrac{1}{3} \times 240\), or the relative frequency \(\dfrac{112}{240}\)

    oe.

  2. 1 mark

    A1 for the expected number 80, or the relative frequency 0.467 compared with \(\dfrac{1}{3}\) (0.333)

    Accept awrt 0.47 and 0.33. A correct expected number with no working seen scores M1A1.

  3. 1 mark

    B1 for a comparison and an assessment, e.g. 112 is much more than the 80 expected by guessing, so the results do not support the supermarket's statement (people seem to be able to tell the difference, or the test was biased)

    ft their expected number. The direction of the difference must be correct. Accept 'many more people chose the different cup than would be expected by chance'. B0 for 'the results support the statement'. B0 for an assessment with no figures. Answer only (a decision with no expected number or relative frequency) scores 0 for the first three marks.

  4. 1 mark

    B1 for a possible reason to do with how the test was carried out, e.g. the two colas may look different (colour, fizz, temperature), so people could pick out the different cup by looking / the different cup may always have been in the same position / people could see the bottles or the cups being filled / people who had done the test may have told others which cup was different / the cups were marked or labelled

    oe. The reason must relate to how the test was done and explain how people could pick out the different cup without tasting a difference. B0 for 'people can taste the difference' (not about the method), 'chance' alone or 'the sample was too small'.

Ready to try the rest? Every answer you write is marked against the mark scheme, so you can see exactly where the marks are.

Study Helper Hints first, answers after you try

Stuck on this one? Ask for a hint and I’ll point you in the right direction, without giving the answer away. Once you’ve checked your answer, I’ll show you how the marks are awarded.